In an era where ChatGPT and Claude dominate the AI landscape, there's a powerful alternative that many people don't know about: running large language models (LLMs) directly on your own computer. This isn't just for tech wizards anymore - with the right tools, anyone can have their own private AI assistant running locally.
Why Your Next AI Assistant Should Run Locally
Complete Privacy - Your Data Stays Yours
Your conversations never leave your computer. No data is sent to external servers, which means sensitive business information stays private, personal conversations remain confidential, there are no data retention policies to worry about, and you get full compliance with data protection regulations.
Zero Ongoing Costs - Pay Once, Use Forever
After the initial setup, there are no subscription fees or API costs. Use your AI as much as you want without worrying about monthly subscription payments, per-token pricing, usage limits or rate restrictions, or credit card requirements.
Unlimited Usage - No More Rate Limits
No daily message limits, no throttling, no waiting in queues. Your local LLM is always available, even without an internet connection.
Customization Freedom - Make It Yours
You can fine-tune models for specific tasks, run multiple models simultaneously, and experiment with different configurations without restrictions.
Offline Capability - Work Anywhere
Once downloaded, your LLM works completely offline - perfect for travel, areas with poor connectivity.
Understanding Model Sizes and Hardware Requirements
The performance of local LLMs heavily depends on two factors: the model size (measured in billions of parameters) and your computer's specifications.
3B Parameter Models (Entry Level)
RAM Required: 8 GB minimum. GPU: Optional (helps with speed). Storage: 2–4 GB. Best for: Basic tasks, coding assistance, quick Q&A. Examples: Llama 3.2 3B, Phi-3 Mini.
7–8B Parameter Models (Sweet Spot)
RAM Required: 16 GB minimum. GPU: 6–8 GB VRAM recommended. Storage: 4–8 GB. Best for: General-purpose tasks, balanced performance. Examples: Mistral 7B, Llama 3.1 8B.
13B Parameter Models (Advanced)
RAM Required: 32 GB minimum. GPU: 12 GB VRAM recommended. Storage: 8–14 GB. Best for: Complex reasoning, professional use. Examples: Llama 2 13B, WizardLM 13B.
70B+ Parameter Models (Professional)
RAM Required: 64 GB minimum. GPU: 24 GB+ VRAM (or multiple GPUs). Storage: 40–80 GB. Best for: Production environments, highest quality outputs. Examples: Llama 3.1 70B, Mixtral 8x22B.
Step-by-Step Installation Guide
Method 1: Ollama (Recommended for Beginners)
Ollama is the easiest way to get started with local LLMs. It handles everything automatically.
Install Ollama on macOS/Linux:
curl -fsSL https://ollama.com/install.sh | shOn Windows, download the installer from ollama.com/download.
Download your first model by opening your terminal and running:
# For 8 GB RAM systems
ollama pull llama3.2:3b

# For 16 GB RAM systems (recommended)
ollama pull mistral:7b

# For 32 GB+ RAM systems
ollama pull llama3.1:70b
The download might take 5–30 minutes, depending on model size and internet speed.
Start chatting:
ollama run mistral:7bYou'll see a prompt where you can start chatting immediately:
>>> Hello! How are you today?For a ChatGPT-like experience, install Open WebUI:
docker run -d -p 3000:8080 --add-host=host.docker.internal:host-gateway \
  -v open-webui:/app/backend/data --name open-webui \
  --restart always ghcr.io/open-webui/open-webui:main
Then visit http://localhost:3000 in your browser.
Method 2: LM Studio (Best for Windows Users)
LM Studio provides a beautiful GUI for managing local LLMs. Download LM Studio from lmstudio.ai, install and launch the application, browse the model library and click download on your chosen model, then once downloaded click "Load Model" to start chatting.
LM Studio advantages: no command line required, visual model management, built-in performance monitoring, and easy model comparison.
Essential Commands and Configuration
# List installed models
ollama list

# Remove a model
ollama rm llama3.2:3b

# Show model information
ollama show mistral:7b

# Copy a model (for customization)
ollama cp mistral:7b my-custom-model

# Push to Ollama registry (if you've customized)
ollama push my-custom-model
Performance Optimization Tips
Enable GPU Acceleration
For NVIDIA GPUs, verify CUDA is available and Ollama will use it automatically:
# Verify CUDA is available
nvidia-smi

# Ollama automatically uses GPU if available
# Check with:
ollama run mistral:7b --verbose
Apple Silicon (M1/M2/M3/M4): Ollama automatically uses Metal acceleration. No configuration needed!
For AMD GPUs with ROCm:
# Ensure ROCm is installed
rocm-smi

# Set environment variable
export HSA_OVERRIDE_GFX_VERSION=10.3.0  # Adjust for your GPU
Adjust Context Window for Speed
Smaller context windows = faster responses and less RAM usage:
# Create a Modelfile with optimized context
FROM mistral:7b
PARAMETER num_ctx 2048  # Default is usually 4096

# For maximum speed
PARAMETER num_ctx 1024
Trade-off: Smaller windows mean less conversation memory.
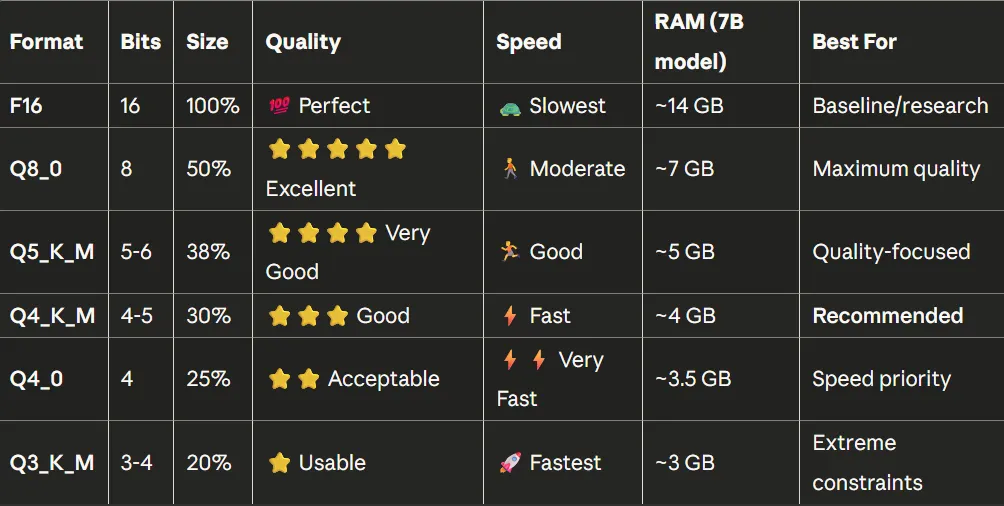
Use Appropriate Quantization Levels
Think of quantization like compressing a high-resolution photo. The original image might be 10MB, but you can compress it to 2MB, and it still looks nearly identical to the human eye. Quantization does the same thing for AI models, but instead of pixels, we're compressing the mathematical weights that make up the model's "brain."
# Download specific quantization
ollama pull mistral:7b-q4_K_M
ollama pull llama3.1:8b-q8_0
Monitor System Resources
On Linux/macOS:
# CPU and RAM monitoring
htop

# GPU monitoring (NVIDIA)
watch -n 1 nvidia-smi

# GPU monitoring (AMD)
watch -n 1 rocm-smi
On Windows, use Task Manager (Ctrl+Shift+Esc) or PowerShell:
Get-Process ollamaOptimize Environment Variables
# Allow multiple models loaded simultaneously
export OLLAMA_MAX_LOADED_MODELS=2

# Increase parallel request handling
export OLLAMA_NUM_PARALLEL=4

# Set custom model storage location
export OLLAMA_MODELS=/path/to/fast/ssd

# Adjust keep-alive time (seconds models stay in memory)
export OLLAMA_KEEP_ALIVE=300
Hardware-Specific Optimizations
For systems with limited RAM: use smaller models (3B-7B), aggressive quantization (Q4), smaller context windows (2048), and close unnecessary applications.
For systems with good GPU but limited RAM: use quantized models (Q4/Q5), let the GPU handle the computation, and use moderate context windows (4096).
For high-end systems: use larger models (70B), higher quantization (Q8/F16), large context windows (16k-128k), and run multiple models simultaneously.
Local vs Cloud LLMs: When to Use Each
Use local LLMs for privacy-critical work (medical, legal, financial data), offline environments (air-gapped systems, travel), high-volume usage to save on API costs, custom requirements like fine-tuning and specialized prompts, learning and experimentation, and data sovereignty for regulatory compliance.
Use cloud LLMs for maximum quality on critical business decisions, access to the latest capabilities and newest models, situations with limited hardware like basic laptops, collaborative features and team workspaces, mobile access with full-featured apps, and when you want no maintenance with automatic updates.
The Hybrid Approach
Use local for draft generation and iteration, code autocomplete and snippets, internal documentation, and brainstorming sessions. Use cloud for final content review, complex reasoning tasks, public-facing communications, and latest model capabilities.
Cost example: Company cloud LLM at $200/month versus a hybrid approach at $40/month cloud plus local results in savings of $1,920/year.
Final Thoughts
Running LLMs locally is a game-changer. What once required massive data centers is now possible on your laptop. Whether you're concerned about privacy, want unlimited usage, need offline capability, or love tech, local LLMs are an incredible alternative.
Start small with 3B or 7B models, experiment with configurations, learn what works for you, and gradually explore advanced use cases.
Remember: quantization makes powerful models accessible, privacy and control are immediate benefits, cost savings compound over time, customization possibilities are endless, and technology keeps improving.
Your AI journey doesn't have to be cloud-dependent. Take control, run it locally, and have fun!